

SEO Spider Crawl Problems.
How to deal with potential SEO Spider crawl problems.
Guide contents 5 sections
●Brief01.Intro02.Status Code 0: no response03.HTTP status codes04.The 429 error and ShopifyWhat to do when SEO Spider crawls only one page or gets stuck: the most common causes (robots.txt, DNS, timeouts, refused connections, 4xx and 5xx errors) and how to fix each. With a focus on the 429 error on Shopify stores and crawler signatures.
Intro
Sometimes Screaming Frog may crawl just one page, or not crawl as expected.
When that happens, the first things to check are the Status and Status Code of the resources returned, to identify the problem and fix it.
Status Code 0: no response
Blocked by Robots.txt
This filter shows every URL blocked by the site’s robots.txt, which stops the Spider from crawling those resources and, as a result, from having them indexed by search engines.
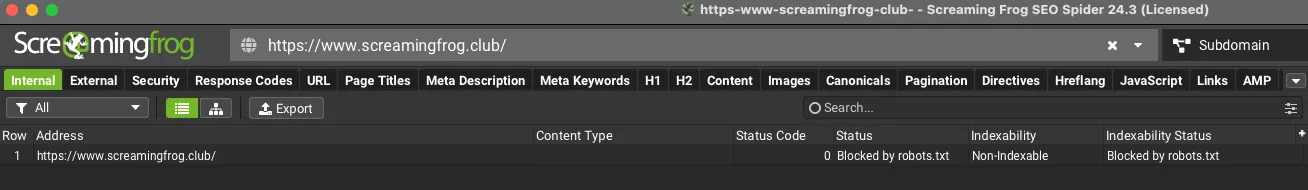
Every “0” in the Status Code column means there was no HTTP response from the server, while the Status column gives the reason. In the example, the Spider’s user agent was blocked by robots.txt with a “disallow” directive and, being blocked, it can’t see the HTTP response.
What to do
You can set SEO Spider to ignore robots.txt from 1Configuration›2robots.txt by choosing Ignore robots.txt, or customise it with a custom robots.txt. By default Screaming Frog follows the “disallow” rules in the robots.txt file.
Further readingCrawling staging sites.Robots.txt, authentication, noindex and nofollow: how to crawl a protected site before it goes live.Read the guideDNS Lookup Failed
The site wasn’t found, because of a typo in the domain or a lack of network connection.

What to do
Check that the domain is spelled correctly and that the site loads in your browser. If it doesn’t load in the browser either, there may be connectivity problems; if it opens fine, check whether antivirus software or a firewall is blocking SEO Spider.
Connection Timeout
Screaming Frog requested the HTTP response from the server but didn’t receive it within 20 seconds. To get around it you can increase the Response Timeout in the configuration or reduce the Spider’s speed, so as not to overload the server and give it more time to respond.

What to do
- Check the site’s load times in the browser: if they’re very long, increase the timeout in 1Configuration›2Spider›3Advanced and reduce the crawler speed in 1Configuration›2Speed to ease the load on the server.
- Check whether you can crawl other sites with Screaming Frog. If the problem is widespread it could be antivirus or firewall: try creating an exception for Screaming Frog.
- If that doesn’t fix it either, there’s probably a network or local issue. For example, check whether the proxy is enabled in 1File›2Settings›3Proxy: if so, try disabling it and restart the crawl.
Connection Refused
Returned when SEO Spider’s connection attempt was refused somewhere between your machine and the website.

What to do
- Can you crawl other websites? If so, check your antivirus and firewall and create an exception for the Spider; if other sites have the same problem, check there isn’t an issue with your network or computer.
- Can you see the page in the browser, or does it return a similar error? If the page loads, change the user agent to Chrome in 1Configuration›2User-Agent.
No Response
SEO Spider is having trouble creating connections or receiving responses. A common cause is the proxy.

What to do
The first thing to check is the proxy (1File›2Settings›3Proxy): try disabling it. If it isn’t set up correctly, SEO Spider may not be able to send or receive requests.
HTTP status codes
Success (2xx)
The requested URL was received, understood, accepted and processed successfully. If the crawl still stops at the first page, here are the checks I suggest.
What to do
- Does the page have a “nofollow” meta robots directive (or one in the HTTP header), or do all the links on the page have rel=“nofollow”? In that case set SEO Spider to follow Internal/External nofollow links in 1Configuration›2Spider›3Crawl: by default Screaming Frog respects “nofollow”.
- Does the site have JavaScript links? Try disabling JavaScript and viewing the pages in the browser. If the links disappear, enable JavaScript rendering in 1Configuration›2Spider›3Rendering. By default SEO Spider only crawls
<a href="">,<img src="">and<link rel="canonical">links in the HTML source and doesn’t read the DOM. - Check the 1Configuration›2Spider›3Limits section, especially “Limit Crawl Depth” and “Limit Crawl Total”: if they’re set to 0 or 1, SEO Spider crawls a single URL.
- Does the site require cookies? Try viewing the page with cookies disabled in the browser: SEO Spider may be served a different page with no links. To fix it, set Cookie Storage to “Session Only” in 1Configuration›2Spider›3Advanced.
- What’s in the Content Type column? If it’s empty, enable JavaScript rendering and restart the crawl. This happens when the HTTP header doesn’t specify the content type and SEO Spider doesn’t know whether the URL is an image, a PDF or an HTML page, so it doesn’t parse it for more links. With rendering on, the tool also checks for a
<meta http-equiv>in the<head>. - Are there age restrictions? Try setting the user agent to Googlebot (1Configuration›2User-Agent): the server might serve the HTML to search engine bots without asking for age.
Redirection (3xx)
A redirect was detected, such as a 301 or 302. Ideally every internal link should point to a 200 response and avoid extra hops for the Spider, to protect Crawl Budget.

What to do
- Check the redirect target in the URL’s outlinks. If there’s a loop, SEO Spider can’t complete the crawl.
- External tab: SEO Spider treats subdomains as external and doesn’t crawl them by default. To include them, enable Crawl All Subdomains in 1Configuration›2Spider›3Crawl.
- Does the site require cookies? Try disabling them in the browser: if you hit the problem, set Cookie Storage to “Session Only” in 1Configuration›2Spider›3Advanced. This happens when SEO Spider is redirected to a URL that sets a cookie, but the cookie isn’t accepted.
Client Error (4xx)
The server can’t or won’t process the request and denies SEO Spider the requested URL.

What to do
- 403 Forbidden: if the page loads in the browser, try setting Chrome as the user agent (1Configuration›2User-Agent). The site is probably denying the page to SEO Spider for security reasons.

- 404 Not Found: the server says the page doesn’t exist. If nothing changes with the Chrome user agent either, the problem is probably the site. If instead with Chrome the page is returned (or you can see it in the browser) and the crawl starts, the server was blocking our user agent for security reasons.
- 429 Too Many Requests: too many requests were sent to the server in a given period. Can you see the site in the browser, or does it show a similar error? Reduce the crawl speed and/or try a different user agent, such as Chrome or Googlebot. If the site runs on Shopify, read the next section.
Server Error (5xx)
The server failed to fulfil an apparently valid request. Common responses such as 500 Internal Server Error, 502 Bad Gateway and 503 Service Unavailable fall into this group.

What to do
- Can you see the site in the browser, or is it down? If the page loads, change the user agent to Chrome (1Configuration›2User-Agent).
The 429 error and Shopify
If you crawl a Shopify store, especially a staging theme or a store that isn’t live yet, it’s easy to see a long series of 429 Too Many Requests after a few dozen URLs. Shopify applies very aggressive rate limiting to crawlers it doesn’t recognise, and slowing SEO Spider down often isn’t enough: the crawl becomes painfully slow and the data stays incomplete.
The official solution is crawler signatures (crawler access). Shopify lets you generate cryptographic signatures that authenticate your crawler on the store: when SEO Spider sends them, Shopify recognises it as an authorised tool and doesn’t throttle it. According to Shopify’s documentation, if the crawler gets rate-limiting errors the signature isn’t valid.
Creating the signature in Shopify
- In the Shopify admin go to Online Store › Preferences.
- In the Crawler access section click Create signature.
- Give the signature a descriptive name, for example “Screaming Frog staging”.
- Select the connected domain you’ll use it on: each signature works for one domain only.
- Choose the expiry (up to three months) and click Create.
- Copy the Signature-Input and Signature values.
According to Shopify, the main features of signatures are:
- Secure authentication: signatures are cryptographic and can’t be forged.
- Controlled expiry: they expire automatically after the chosen period, up to three months, and can’t be renewed or extended. For a new date you create a new signature and update the tool; the old one keeps working until its original expiry.
- Central management: you’ll find them all in Crawler access, where you can also copy the values again if you’ve lost them.
- Custom name: helps you remember which tool or project it’s for.
- Domain-bound: it only works on the associated domain.
Signatures don’t give access to Checkout and aren’t needed by search engines and LLMs, which index the store without them.
Setting the HTTP headers in Screaming Frog
Every SEO Spider request must include three HTTP headers. Go to 1Configuration›2HTTP Header, click Add for each one and enter the name and value:
- Signature-Input: the value copied from the Shopify admin.
- Signature: the value copied from the Shopify admin.
- Signature-Agent:
"https://shopify.com", quotes included.
The result looks like this. The Signature-Input and Signature values here are only examples: always use the ones generated for your store.
Signature-Input: sig1=("@authority" "signature-agent");created=1760600000;expires=1768376000;keyid="…";alg="ed25519";tag="web-bot-auth"
Signature: sig1=:…valore-base64-copiato-da-shopify…:
Signature-Agent: "https://shopify.com"
If you keep getting 429 errors, Shopify suggests checking that:
- the header format is correct, with no spaces or characters lost when copying and pasting;
- all three headers are sent with every request;
- the signature hasn’t expired (the date is in Crawler access);
- you’re crawling the exact domain associated with the signature, not another domain or the myshopify.com domain.
Questions about SEO Spider Crawl Problems?
These guides come from real projects. If something in your crawl doesn’t add up, or you want to apply this process to your site, get in touch.
 Author.Raffaele Visintin.Search & Strategic Marketing Advisor
